
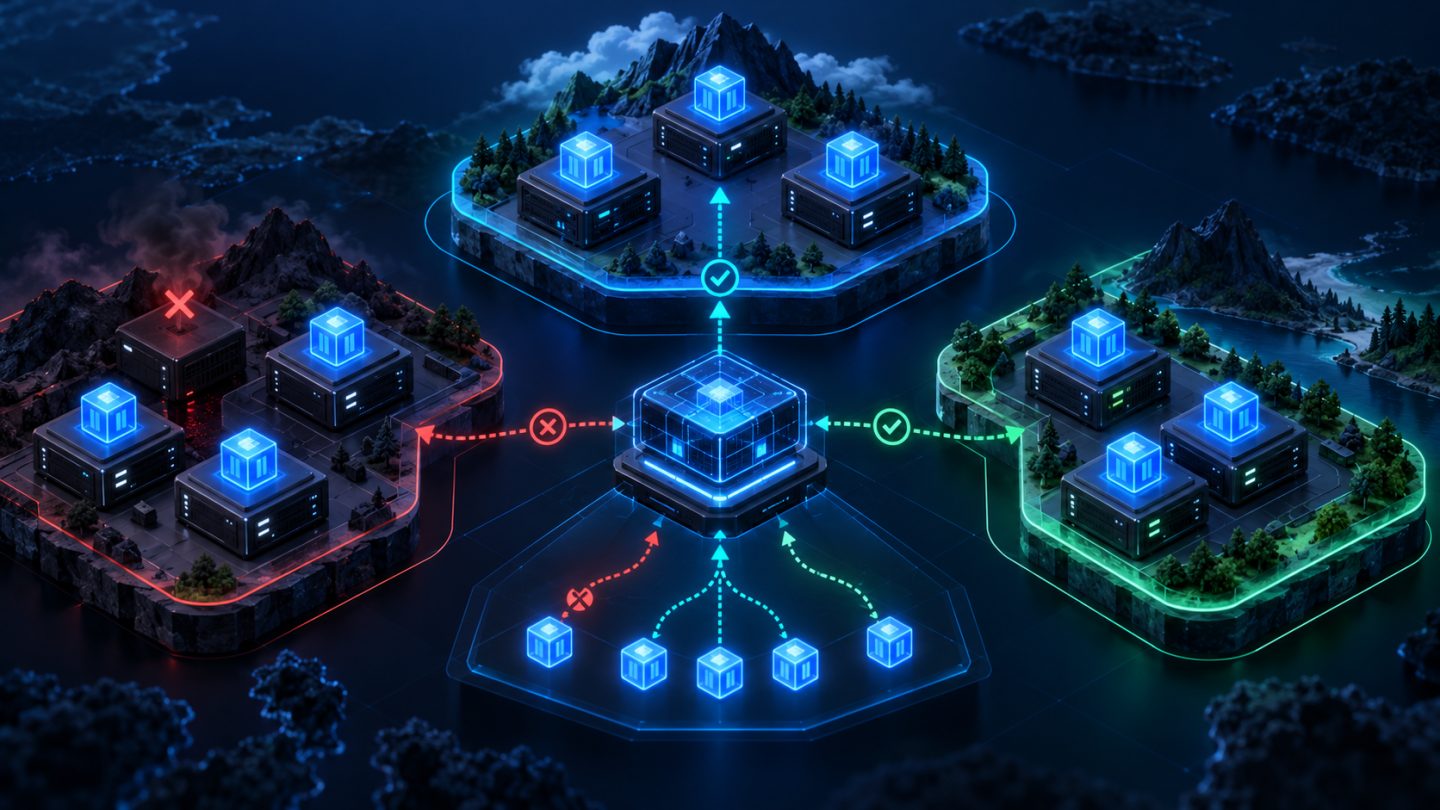
Multiple replicas do not automatically provide high availability. If the scheduler places every Pod on one node or availability zone, a single failure can remove the service. Kubernetes Topology Spread Constraints express desired distribution across zones, nodes, or custom fault domains—but their effectiveness depends on correct labels, selectors, real capacity, and an explicit choice between rejecting placement and scheduling despite imbalance.
This guide follows official documentation for Pod Topology Spread Constraints and kube-scheduler configuration. Some advanced fields depend on release and feature gates; use kubectl explain and documentation matching the cluster minor version.
1. What is a fault domain?
A topology domain is one value of a node label. For topology.kubernetes.io/zone, nodes sharing a zone value form one domain. For kubernetes.io/hostname, each node is usually a domain.
| Goal | Common topology key | Failure addressed |
|---|---|---|
| Spread across regions | topology.kubernetes.io/region | Region loss, with matching data and network architecture |
| Spread across zones | topology.kubernetes.io/zone | Availability-zone loss |
| Spread across nodes | kubernetes.io/hostname | Node reboot, drain, or failure |
| Spread across racks | Organization-managed label | Rack, power, or switch loss |
Labels help only when they match physical infrastructure and are applied consistently. Naming colocated nodes zone A and zone B does not create fault isolation.
2. A two-level zone and node manifest
apiVersion: apps/v1
kind: Deployment
metadata:
  name: payments-api
spec:
  replicas: 6
  selector:
    matchLabels:
      app: payments-api
  template:
    metadata:
      labels:
        app: payments-api
    spec:
      topologySpreadConstraints:
        - maxSkew: 1
          minDomains: 3
          topologyKey: topology.kubernetes.io/zone
          whenUnsatisfiable: DoNotSchedule
          labelSelector:
            matchLabels:
              app: payments-api
          matchLabelKeys:
            - pod-template-hash
          nodeAffinityPolicy: Honor
          nodeTaintsPolicy: Honor
        - maxSkew: 1
          topologyKey: kubernetes.io/hostname
          whenUnsatisfiable: ScheduleAnyway
          labelSelector:
            matchLabels:
              app: payments-api
          matchLabelKeys:
            - pod-template-hash
      containers:
        - name: app
          image: registry.example.com/payments/api@sha256:<digest>
          resources:
            requests:
              cpu: 250m
              memory: 256Mi
This example requires the current revision to span at least three zones with maximum skew one. Inside zones, the scheduler prefers different nodes but can still schedule when node-level balance is impossible. It is illustrative: a two-zone cluster cannot use minDomains: 3 unchanged.
3. Understand maxSkew and the global minimum
For a hard constraint, the scheduler compares matching Pod count in the target domain with the global minimum among eligible domains. If three zones contain 2, 2, and 1 Pods, the minimum is 1. Placing the next Pod into a zone with 2 creates skew 2 and violates maxSkew: 1; placing it in the zone with 1 yields 2, 2, and 2.
minDomains declares the minimum expected eligible domains and is used only with DoNotSchedule. If fewer domains are eligible, the global minimum becomes zero, preventing a cluster missing zones from silently appearing balanced. The Pod may stay Pending—which is correct when domain diversity matters more than running at any cost.
4. DoNotSchedule or ScheduleAnyway?
| Mode | Behavior | Fit |
|---|---|---|
DoNotSchedule | Filters nodes that would violate the constraint | Concentration into too few fault domains is unacceptable |
ScheduleAnyway | Schedules while preferring nodes that reduce skew | Workload capacity matters more than strict balance |
A hard constraint can turn missing capacity into Pending Pods and stall a rollout. A soft constraint can keep all replicas running in one zone after capacity loss. Choose from SLO and failure policy. Hard zone spread and soft node spread are a useful starting point for many stateless services, not a universal rule.
5. The selector must count the intended workload
labelSelector defines the Pods counted. An overly broad selector lets other workloads distort skew. A selector that does not match the incoming Pod produces a “ghost Pod”: placement occurs without changing the count as expected, allowing Pods to accumulate in one domain.
Keep the Deployment selector, Pod template labels, and spread selector in one contract. The scheduler counts matching Pods in the incoming Pod's namespace.
6. matchLabelKeys and rolling updates
matchLabelKeys takes values from the incoming Pod and merges them into the selector. Using pod-template-hash can calculate skew per Deployment revision, avoiding surprising interaction between old and new revisions during rollout.
This is a semantic choice: requirements that balance old and new Pods together may need another selector strategy. Test maxSurge, maxUnavailable, and rollback. Do not place the same key in both labelSelector and matchLabelKeys, and confirm cluster-version support.
7. Eligible domains depend on node policy
The scheduler does not count every zone on a cloud diagram. Eligible domains come from nodes carrying the topology label and satisfying Pod node-affinity and taint inclusion rules. nodeAffinityPolicy and nodeTaintsPolicy control whether those rules are honored while calculating domains.
- A node missing the topology key is bypassed and cannot host the Pod for that constraint.
- A label typo can make an entire node pool disappear.
- A taint without a toleration can remove one zone from eligibility.
- Node affinity may select an instance type available in only one zone.
Audit labels, taints, affinity, and capacity together. A syntactically valid constraint can still be impossible.
8. Multiple constraints are combined with AND
With both zone and hostname constraints, a candidate node must satisfy both. This is stronger than independent preferences and can conflict. The zone needing a Pod may contain only nodes that violate hard hostname skew or lack requested resources.
Use scheduler events to identify the blocking filter. Do not immediately relax maxSkew; inspect resources, volume topology, taints, affinity, quotas, and image architecture first.
9. Autoscaling and zero-node domains
The scheduler derives topology domains from existing nodes. If a zone's node group has scaled to zero, that domain may be absent from spread calculations; the autoscaler must understand the potential node group and topology to create capacity in the right place.
Test from zero rather than only scaling down a healthy cluster. Ensure autoscaler node templates carry correct labels and taints, resource requests are accurate, and the storage class can provision volumes in the new zone.
10. The scheduler does not rebalance running Pods
Constraints apply when a new Pod is scheduled. If scale-down or recovery leaves an imbalance, the scheduler does not move running Pods solely to restore symmetry. A rollout, natural rescheduling, or a properly configured Descheduler can rebalance; evictions must respect disruption budgets and available capacity.
Do not evict simply because a histogram is imperfect. Evictions discard caches, create startup load, and can affect SLOs. Use thresholds, maintenance windows, and rate limits.
11. Spread does not replace PDB or anti-affinity
- Topology spread controls distribution at placement.
- PodDisruptionBudget limits concurrent voluntary disruptions, not node or zone failure.
- Pod anti-affinity repels Pods by label relationship and can be stricter and costlier to schedule.
- Resource requests expose capacity needs to the scheduler.
- Storage topology determines whether stateful Pods can run elsewhere.
High availability also needs probes, multiple endpoints, load balancing, database replication, and multi-zone dependencies. Spreading frontends does not help when every replica relies on a single-zone database.
12. Observe and roll out
- Inventory zone and node-pool labels and detect missing values.
- Run soft constraints in staging and inspect placement per revision.
- Test replica scaling, rolling updates, and node drains.
- Simulate zone loss, capacity loss, and node groups at zero.
- Canary hard constraints and alert on Pending Pods and stalled rollouts.
- Measure replicas, ready endpoints, traffic, and errors per domain.
kubectl get nodes -L topology.kubernetes.io/zone,kubernetes.io/hostname
kubectl get pods -n payments -l app=payments-api \
  -o wide
kubectl describe pod <pending-pod>
Production checklist
- Topology labels represent real fault domains and exist on every relevant node.
- Pod templates match their own constraint selectors.
maxSkewandminDomainsmatch actual zones and capacity.- Hard and soft behavior follows the SLO and failure policy.
matchLabelKeysrollout semantics have been tested.- Affinity, taints, volume topology, and requests are compatible.
- Autoscaling works when a domain starts at zero nodes.
- PDB and rollout settings do not deadlock hard spread.
- Alerts detect imbalance, Pending Pods, and missing ready endpoints by zone.
- Node drain and zone loss have been exercised, not merely inspected.
Conclusion
Topology Spread Constraints turn “do not put every egg in one basket” into a scheduler policy. The YAML works only when selectors count correctly, node labels reflect infrastructure, capacity exists, and the team decides when a Pod should remain Pending. Combining zone and node spread with PDBs, autoscaling, storage topology, and failure exercises creates demonstrable high availability.
No comments yet. Be the first to share your thoughts.