
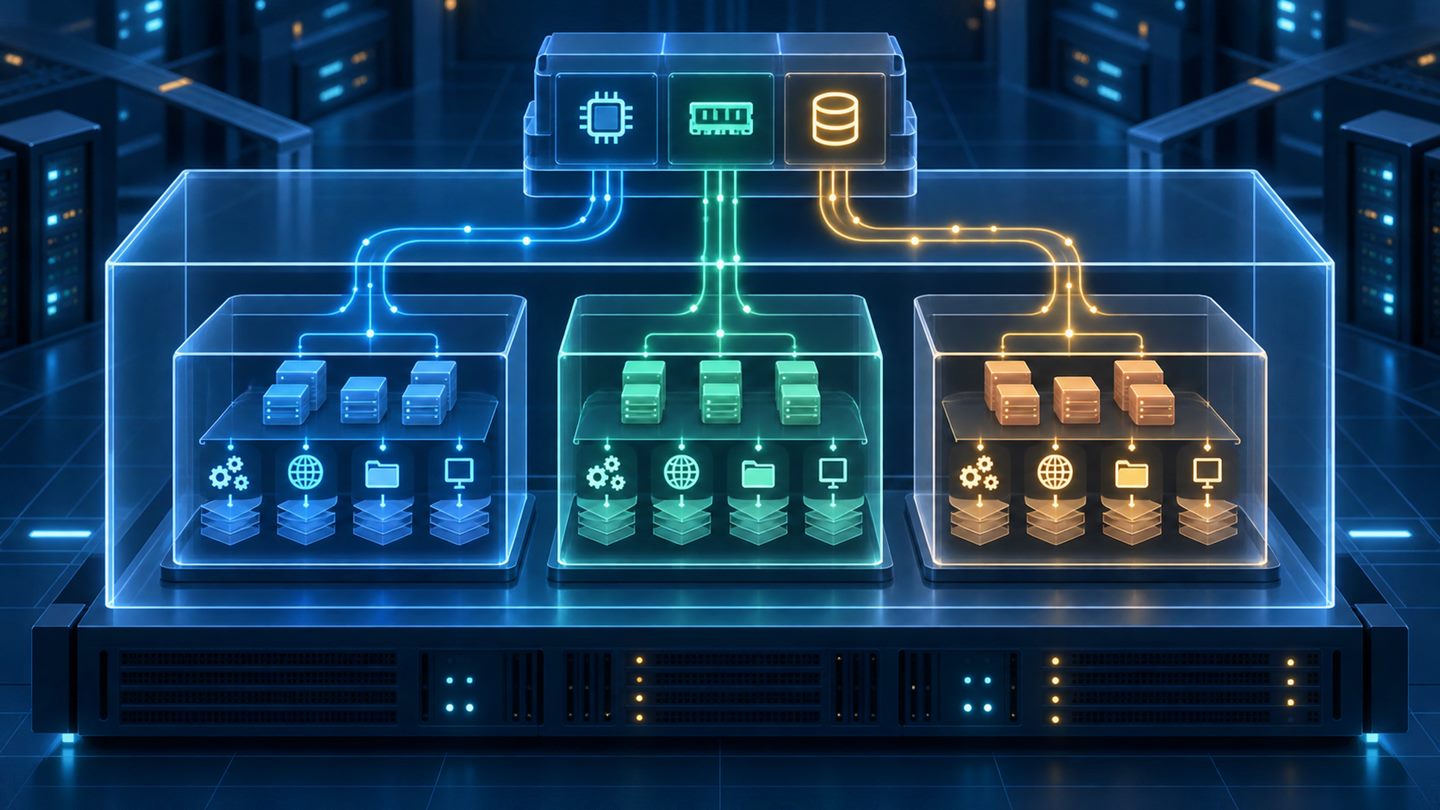
A container is not a miniature virtual machine. Most Linux containers share the host kernel, while each process group sees a constrained resource scope and consumes only the budget assigned to it. The two kernel mechanisms at the center of this model are namespaces and cgroups.
Namespaces change what a process can see: PIDs, mounts, networking, hostnames, IPC, user IDs, and other resources. cgroups arrange processes in a tree to measure, prioritize, and limit CPU, memory, or I/O. The mechanisms complement each other, but together they are still not a complete security boundary.
1. Separate the “view” from the “budget”
| Mechanism | Main question | Example |
|---|---|---|
| Namespace | Which resources can a process see? | PID list, network interfaces, mount points |
| cgroup | How much may a process group consume? | Memory limit, CPU weight, I/O bandwidth |
| Capabilities/LSM/seccomp | Which actions may a process perform? | Drop privileges, filter syscalls, enforce access policy |
Name isolation and resource control are separate problems. With namespaces but no cgroups, a workload may still exhaust memory or compete aggressively for host CPU.
2. How namespaces work
A namespace wraps a global resource in an abstraction. A process inside appears to have its own instance of that resource. The kernel tracks namespace membership and returns the corresponding view when a process makes a system call or reads interfaces under /proc.
Processes create or join namespaces through APIs such as clone(), unshare(), and setns(). Operators normally use unshare, nsenter, lsns, and container runtimes rather than calling those APIs directly.
| Type | Isolates | Container effect |
|---|---|---|
| PID | Process ID number space | A process can see itself as PID 1 |
| Mount | List of mount points | Root filesystem and volumes differ from the host |
| Network | Interfaces, routing, ports, firewall | Each container gets a network stack |
| UTS | Hostname and domain name | Independent hostname |
| IPC | System V IPC and POSIX queues | Reduces unintended interprocess communication |
| User | UIDs, GIDs, and capabilities | UID 0 inside may map to an unprivileged host user |
| Cgroup | The view of the cgroup tree | Hides unrelated management branches |
| Time | Selected system clocks | Supports clock offsets for appropriate workloads |
3. PID namespaces and the special role of PID 1
A process can have different PIDs when viewed from nested PID namespaces. The first process in a new namespace has PID 1 from the inside. It has important responsibilities for reaping terminated child processes and handling signals.
If the main application does not fulfill the init role, zombie processes can accumulate or stop signals may not be forwarded as expected. A runtime can insert a small init, or the application must reap children and react correctly to SIGTERM.
4. Mount and network namespaces
A mount namespace separates the list of mounts visible to processes. This enables a private root filesystem, configuration bind mounts, and data volumes. A mount does not make data inherently safe: file permissions, read-only mode, propagation, and exposed bind paths still require deliberate configuration.
A network namespace provides separate network devices, routing tables, firewall rules, and port space. A veth pair often connects a container namespace to a bridge or the host namespace. A service listening on port 8080 internally is not automatically reachable externally; the runtime must configure a path and policy.
5. A user namespace does not turn container root into host root
User namespaces map UIDs and GIDs between inner and outer scopes. A process can be UID 0 in its namespace while mapping to an unprivileged UID on the host. Capabilities are also evaluated relative to the relevant user namespace.
This is useful privilege reduction, not an absolute guarantee. The kernel remains shared, and syscalls, devices, filesystem mounts, and runtime settings determine the attack surface. Run applications as non-root where possible, drop unnecessary capabilities, and avoid privileged mode.
6. cgroup v2: one unified management tree
cgroup v2 organizes processes in a single hierarchy. The core manages tree structure and membership; controllers handle individual resource classes. A controller enabled at a parent distributes or constrains resources below it, and a child cannot override a tighter ancestor limit.
Common files include:
cgroup.controllers: controllers available to descendants.cgroup.subtree_control: controllers enabled for child cgroups.cgroup.procs: PIDs belonging to the cgroup.cpu.maxandcpu.weight: CPU quota and weight.memory.max,memory.high, andmemory.current: hard limit, pressure boundary, and current use.io.maxandio.stat: per-device I/O limits and statistics.pids.max: process-count limit that helps contain fork bombs.
7. Safe inspection on a Linux machine
# Namespaces for the current process
ls -l /proc/self/ns
lsns

# cgroup filesystem type and available controllers
stat -fc %T /sys/fs/cgroup
cat /sys/fs/cgroup/cgroup.controllers

# The current process's cgroup
cat /proc/self/cgroup

# System-wide resource pressure, when PSI is available
cat /proc/pressure/cpu
cat /proc/pressure/memory
These commands mainly read state. Do not write directly into a production cgroup tree managed by systemd or a container runtime. Out-of-band changes can be overwritten, corrupt accounting assumptions, or stop services.
8. Limits, reservations, and pressure differ
A hard limit says “do not exceed this,” while a weight or reservation influences priority under contention. Very low limits can produce OOM kills or throttling even when the host has spare capacity; no limits allow one faulty workload to affect the whole machine.
Read memory.current alongside OOM events, CPU throttling, I/O latency, and Pressure Stall Information to distinguish insufficient capacity from bad limits. Compare container metrics with host metrics because namespace-scoped observations may differ from the node's view.
9. A container is not a complete sandbox
Namespaces and cgroups do not filter every syscall, automatically remove capabilities, control every file path, or patch kernel vulnerabilities. A defensive configuration combines layers:
- Minimal, updated images that contain no secrets.
- An unprivileged user; user namespaces or rootless mode where suitable.
- Dropped capabilities, especially avoiding
CAP_SYS_ADMINand privileged containers. - Read-only filesystems, explicit mounts, and no host management socket inside the container.
- seccomp for syscall reduction; SELinux or AppArmor for mandatory access policy.
- Resource limits and health checks aligned with measured behavior.
- VMs or separate nodes for workloads with materially different trust levels.
10. Common misconceptions
- “A container has its own kernel”: ordinary Linux containers share the host kernel.
- “Container root is always host root”: mapping and capabilities matter, but container root remains sensitive.
- “A memory limit eliminates OOM”: a workload can be OOM-killed inside its cgroup while the host still has memory.
- “A CPU limit guarantees performance”: a quota sets a ceiling; latency also depends on contention, scheduling, and I/O.
- “No published port means perfect network isolation”: bridges, routes, firewalls, and platform policy still matter.
11. Operations checklist
- Determine whether the host uses cgroup v2 or a legacy/hybrid arrangement.
- Set requests, weights, and limits from measurements rather than copied defaults.
- Limit PIDs, inspect OOM events, and monitor throttling.
- Run as non-root; drop all capabilities and add back only the minimum.
- Do not casually mount the Docker socket,
/proc,/sys, or host devices. - Test shutdown so the application handles
SIGTERMand exits on time. - Let a runtime, orchestrator, or systemd manage cgroups in production.
- Evaluate VMs or purpose-built sandboxes for untrusted code.
References
- Linux manual: namespaces(7)
- Linux kernel documentation: Control Group v2
- Linux manual: capabilities(7)
Conclusion
Namespaces create a private resource view; cgroups assign a budget and collect measurements for process groups. A container runtime combines those mechanisms with filesystems, networking, and additional policy layers. Understanding each boundary helps operators set better limits, investigate incidents accurately, and avoid confusing container convenience with an absolute sandbox.




No comments yet. Be the first to share your thoughts.