
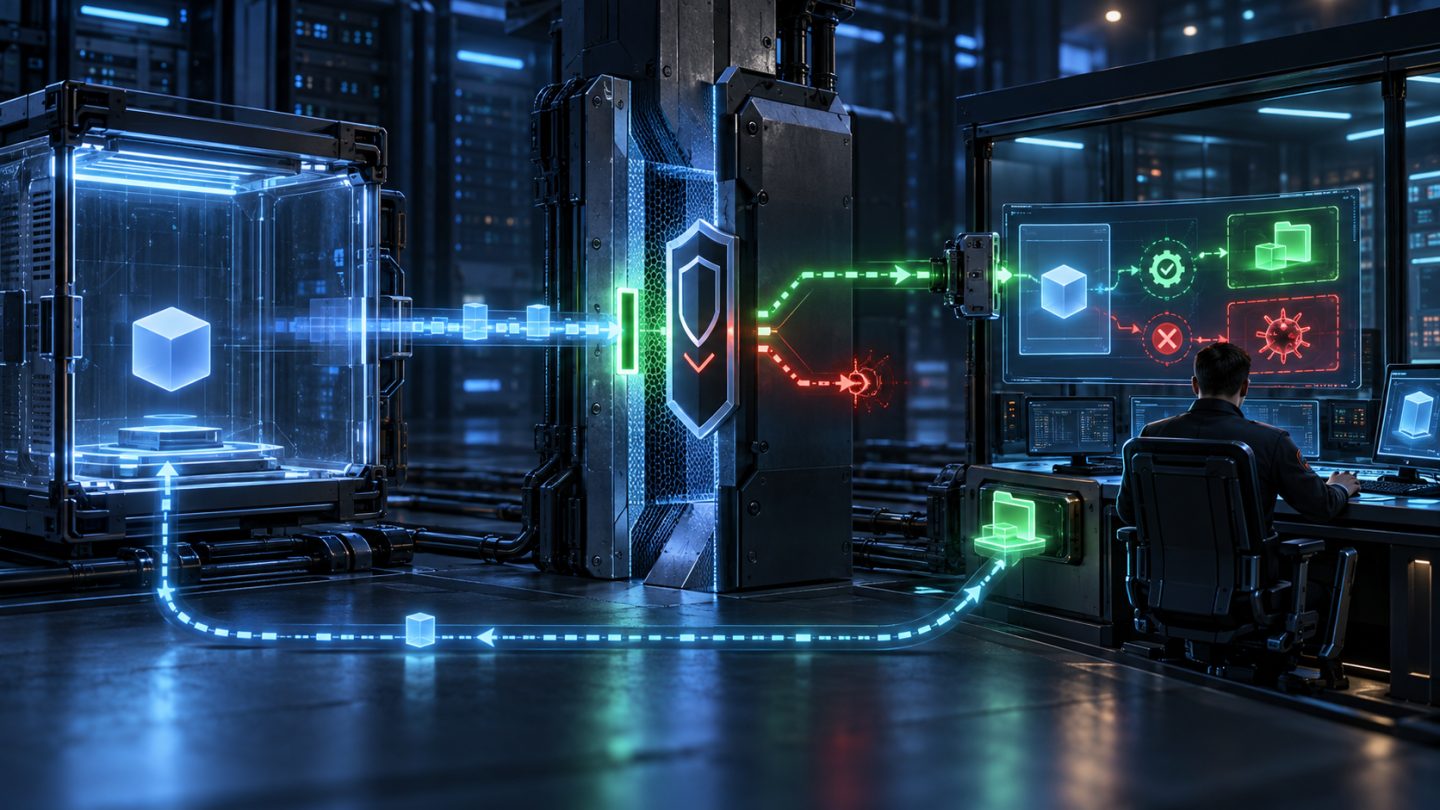
A sandboxed process calls openat(), mount(), or mknod(). The seccomp filter should not let the syscall execute directly, but returning an error would break the workload. Seccomp user notification lets the kernel pause that thread, send the request to a user-space supervisor, and receive a controlled result.
This is useful for container runtimes, compatibility layers, and privilege separation. It is also frequently misrepresented as a dynamic syscall firewall. This guide builds the correct model and covers listener lifecycle, NOTIF_RECV, ID_VALID, NOTIF_SEND, NOTIF_ADDFD, event loops, and critical races. It is based on the Linux kernel Seccomp BPF documentation, seccomp_unotify(2), and seccomp(2).
1. What user notification solves
Classic seccomp BPF sees the syscall number, architecture, instruction pointer, and raw argument-register values. A filter cannot dereference pointers, open files, or call external services. It can allow, return errno, trap, log, or kill, but it cannot perform a controlled operation on behalf of a target.
SECCOMP_RET_USER_NOTIF divides the job:
- The target installs a filter and runs with restricted privileges. A selected syscall blocks in the kernel.
- The supervisor owns a listener FD, receives metadata, performs an operation for the target or emulates a result, and sends a response.
A container runtime can, for example, open a reviewed resource in the appropriate namespace and inject its descriptor rather than allowing the container to open that resource directly.
2. It is not a security-policy engine
User notification must not be the only boundary deciding whether a syscall is safe.
A supervisor can read a string from target memory, approve it, and respond with SECCOMP_USER_NOTIF_FLAG_CONTINUE. While the calling thread is blocked, another thread in the process can rewrite that memory. The kernel then executes the original syscall with different bytes: a TOCTOU race.
The sound model is a privileged supervisor performing a specific action for a less-privileged target while kernel permissions, namespaces, LSMs, capabilities, and filesystem permissions remain the enforcement layers. If CONTINUE is used, pointer arguments must be assumed mutable and another mechanism must still reject unsafe state.
3. Create the listener FD
The filter returns SECCOMP_RET_USER_NOTIF for a narrow syscall set. Install it with SECCOMP_FILTER_FLAG_NEW_LISTENER:
int listener = syscall(
    SYS_seccomp,
    SECCOMP_SET_MODE_FILTER,
    SECCOMP_FILTER_FLAG_NEW_LISTENER,
    &prog
);

if (listener == -1) {
    /* fail closed */
}
The target needs PR_SET_NO_NEW_PRIVS or the capability required by seccomp's contract. Only one listener filter may be installed for a thread. A listener belongs to a filter, not one target; if the target forks and inherits the filter, events from multiple tasks can arrive on the same FD.
A typical bootstrap process installs the filter, passes the listener to the supervisor over a Unix socket with SCM_RIGHTS, and drops remaining privileges. Sending the integer FD over a pipe is wrong because descriptor numbers are local to each process table.
4. Do not hard-code structure sizes
Notification structures can grow. Ask the running kernel for their sizes:
struct seccomp_notif_sizes sizes = {0};

if (syscall(SYS_seccomp, SECCOMP_GET_NOTIF_SIZES,
            0, &sizes) == -1) {
    /* unsupported or fatal */
}

struct seccomp_notif *req = calloc(1, sizes.seccomp_notif);
struct seccomp_notif_resp *resp = calloc(1, sizes.seccomp_notif_resp);
Zero the complete request buffer before each SECCOMP_IOCTL_NOTIF_RECV. Modern kernels can return EINVAL when input fields that should be zero are not. Cap allocations and stop safely if reported sizes are unreasonable.
5. Notification lifecycle
- The target invokes a syscall and its filter returns
USER_NOTIF. - The kernel creates an
idcookie, blocks the thread, and wakes the listener. - The supervisor calls
SECCOMP_IOCTL_NOTIF_RECV. - It validates architecture, syscall number, and scalar arguments.
- If pointers matter, it reads a bounded snapshot from target memory.
- It checks the cookie with
SECCOMP_IOCTL_NOTIF_ID_VALID. - It emulates success or failure, injects an FD, or very carefully continues the syscall.
NOTIF_SENDor an atomic ADDFD operation releases the target.
The cookie is unique only for its filter. Do not treat the TID as notification identity or cache decisions by TID, because thread IDs can be recycled.
6. Supervisor-loop skeleton
for (;;) {
    memset(req, 0, sizes.seccomp_notif);
    memset(resp, 0, sizes.seccomp_notif_resp);

    if (ioctl(listener, SECCOMP_IOCTL_NOTIF_RECV, req) == -1) {
        if (errno == EINTR || errno == ENOENT)
            continue;
        fatal("NOTIF_RECV");
    }

    if (req->data.arch != AUDIT_ARCH_X86_64 ||
        req->data.nr != SYS_openat) {
        deny(resp, req->id, EPERM);
    } else {
        handle_open_request(listener, req, resp);
    }

    if (resp->id != 0 &&
        ioctl(listener, SECCOMP_IOCTL_NOTIF_SEND, resp) == -1 &&
        errno != ENOENT) {
        log_error("NOTIF_SEND");
    }
}
Always check arch before the syscall number because another ABI can reuse numbers differently. The BPF filter must perform the same architecture check. Production code also needs shutdown handling, listener hangup, allocation controls, backpressure, and bounded logging.
7. Return success or failure
To emulate an error, place a negative errno in error:
resp->id = req->id;
resp->val = 0;
resp->error = -EACCES;
resp->flags = 0;
To emulate a successful return value:
resp->id = req->id;
resp->val = emulated_result;
resp->error = 0;
resp->flags = 0;
If the target dies, receives a signal, or abandons the syscall before the response, NOTIF_SEND can return ENOENT. This is a normal lifecycle race, not necessarily a system failure. Never reuse an old response for a new request.
8. ID_VALID and target memory
seccomp_data.args[] contains register values. For pointer arguments it holds only an address in the target's address space. A sufficiently privileged supervisor may read through /proc/<tid>/mem or an appropriate API, but it must:
- cap lengths and require terminators for strings;
- copy once into private memory and parse the immutable snapshot;
- never directly dereference a target address;
- call
SECCOMP_IOCTL_NOTIF_ID_VALIDafter reading and before using bytes; - discard work if the cookie is no longer valid.
__u64 id = req->id;
if (ioctl(listener, SECCOMP_IOCTL_NOTIF_ID_VALID, &id) == -1) {
    /* target abandoned the syscall; discard copied data */
    return;
}
ID_VALID helps prevent acting on a recycled TID, but it does not make CONTINUE race-free. Another thread can still change memory after validation and before the kernel consumes the pointer.
9. ADDFD: the better open emulation
Since Linux 5.9, SECCOMP_IOCTL_NOTIF_ADDFD can copy a supervisor descriptor into the target's descriptor table. The supervisor opens a resource under its controlled root, namespace, and rules, then injects it:
struct seccomp_notif_addfd add = {
    .id = req->id,
    .srcfd = safe_fd,
    .newfd = 0,
    .newfd_flags = O_CLOEXEC,
    .flags = SECCOMP_ADDFD_FLAG_SEND,
};

int target_fd = ioctl(listener,
                      SECCOMP_IOCTL_NOTIF_ADDFD,
&add);SECCOMP_ADDFD_FLAG_SEND, available since Linux 5.14, injects the FD and sends the response atomically, closing the gap between ADDFD and NOTIF_SEND. Older kernels require a careful state machine that closes descriptors and handles target disappearance.
Do not blindly reuse the target's numeric dirfd in the supervisor: the two processes have different descriptor tables. Define an explicit namespace/root model or use a suitable handle primitive for the threat model.
10. CONTINUE is the dangerous branch
resp->id = req->id;
resp->val = 0;
resp->error = 0;
resp->flags = SECCOMP_USER_NOTIF_FLAG_CONTINUE;
This asks the kernel to execute the original syscall. It fits observation or cases where an independent kernel layer is guaranteed to enforce safety. It does not fit “read a pathname and continue if it has an approved prefix.”
Restrict CONTINUE to a tiny syscall allowlist, audit every call site, and ensure the target cannot install another seccomp filter with a higher-precedence action that bypasses the notifier. If independent enforcement cannot be demonstrated, emulate the operation or deny it.
11. Event loops, timeouts, and backpressure
The listener supports poll/epoll. A pending notification makes it readable; after all targets using the filter terminate and are reaped, it reports hangup. A production design needs:
- per-sandbox in-flight request limits;
- a separate worker pool for blocking operations;
- fail-closed timeouts and cancellation when an ID becomes invalid;
- metrics for RECV-to-SEND latency, queue depth, denials, and ENOENT;
- redaction of pathnames, tokens, and sensitive target data;
- a supervisor crash policy, because targets may otherwise wait indefinitely.
Multiple readers may share a listener because access is synchronized by the kernel, but response routing, lifecycle, and fairness remain application responsibilities.
12. Supervisor privilege model
The supervisor is usually more powerful than its targets, so compromise has a larger blast radius. Reduce exposure:
- intercept only syscalls that truly require emulation;
- separate untrusted parsing from privileged workers where practical;
- drop unused capabilities and apply user/mount namespaces and LSM policy;
- use trusted root directory FDs rather than arbitrary absolute paths;
- allowlist flags instead of forwarding target-controlled bitmasks;
- validate file type with
fstat()after opening; - limit CPU, memory, FDs, and notification rate.
A seccomp filter on the supervisor can reduce its syscall surface too, provided the required ioctls, Unix-socket operations, and filesystem calls remain available.
13. Adversarial tests
- Kill or signal the target after RECV, while reading memory, and before SEND.
- Have one thread rewrite a pathname while another issues the syscall.
- Send an unexpected architecture or syscall number.
- Use unterminated and oversized strings, unmapped page boundaries, and changing memory.
- Fill the FD table, lower
RLIMIT_NOFILE, and make an LSM reject ADDFD. - Slow, restart, or crash the supervisor under a full queue.
- Fork many targets that share one filter.
- Run on kernels without NEW_LISTENER, ADDFD, or ADDFD_FLAG_SEND.
- Attempt to install another seccomp filter or invoke a different syscall ABI.
Run these tests in an isolated VM or namespace with sanitizers, fault injection, and race workloads. The central invariant is that the supervisor never performs a privileged action for an expired notification.
Production checklist
- Check architecture and return USER_NOTIF only for a narrow allowlist.
- Obtain structure sizes with SECCOMP_GET_NOTIF_SIZES.
- Zero request and response buffers on every loop.
- Bound and snapshot all target-memory reads.
- Place ID_VALID between reading and using target data.
- Prefer supervisor-side execution plus ADDFD over CONTINUE.
- Use ADDFD_FLAG_SEND when the kernel supports it.
- Treat ENOENT as a normal lifecycle race.
- Implement timeout, backpressure, metrics, and a crash policy.
- Keep namespaces, LSMs, capabilities, and DAC as the real enforcement layers.
Conclusion
Seccomp user notification is a powerful bridge between a sandbox and a supervisor: a target blocks, the supervisor receives a request, performs a controlled action, and returns the result. Its strongest use is privilege separation and emulation, especially with NOTIF_ADDFD. It does not eliminate shared-memory races and does not replace kernel policy. A sound design narrows intercepted syscalls, validates lifecycle with cookies, prefers acting on behalf of the target, and leaves namespaces, LSMs, capabilities, and filesystem permissions as the final security boundary.




No comments yet. Be the first to share your thoughts.