
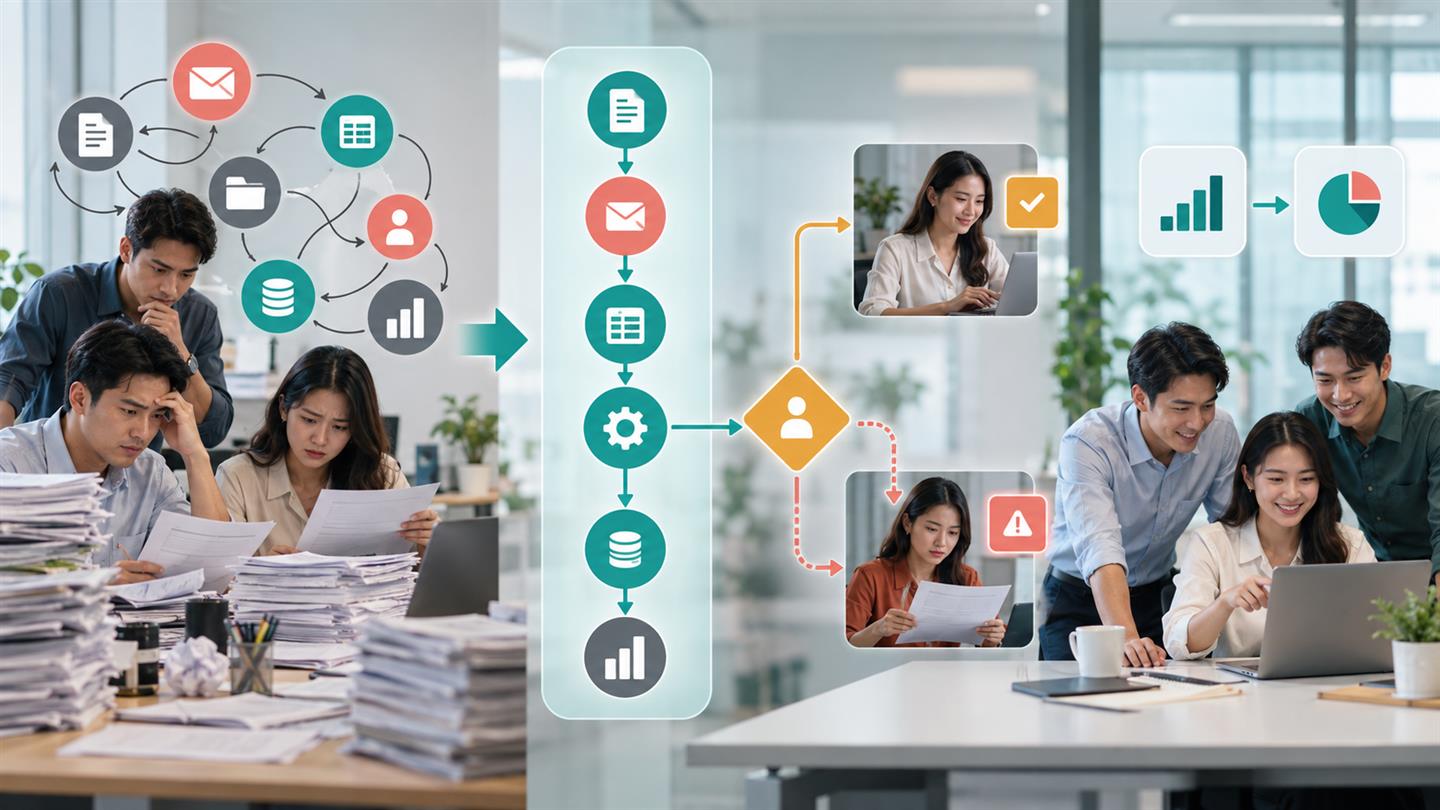
An account request sits in email, a broken laptop is reported through a private message, and an equipment purchase lives in an administration spreadsheet. When an owner is absent or work crosses departments, “What is happening with this request?” becomes difficult to answer. An internal request portal brings intake, responsibility and outcomes together without turning every conversation into a large project.
1. Define the problem before choosing software
Volume alone is not the trigger. Unassigned requests, duplicate submissions, information scattered outside the record and closures without confirmation also indicate a process problem. A new tool helps only when the organization agrees who receives, approves, executes and closes each type of work.
Atlassian describes service request management around repeatable submission, approval, fulfillment and closure. The implementation model below is an editorial proposal: examples and pilot milestones are illustrative, not customer results or performance guarantees.
2. Start with a small service catalog
Instead of launching dozens of forms, select three frequent services with clear outcomes and accountable teams, such as equipment provision, software support and account access. Define intake conditions, required information and exclusions for each.
| Request | Input | Confirmed outcome |
|---|---|---|
| Equipment provision | Recipient, equipment type, purpose and required date | Handover record or rejection reason |
| Software support | Application, symptoms, timing and impact | Resolution details and restored usability |
| System access | Recipient, system, role, expiry and approver | Access provisioned with the correct scope and duration |
Provide a separate urgent intake path for widespread incidents. An organization-wide outage should not compete with a request for a new mouse under identical handling rules. Link related incident reports so several teams do not independently investigate the same underlying event.
3. Define workflow and ownership
A minimal flow is Received → Triage → Approval when required → In progress → Awaiting confirmation → Closed. Add “Waiting for requester” or “Canceled” when justified, but avoid inventing a status for every conversation.
Every request needs an accountable team and a current assignee. Transfers retain their reason, timestamp and history. Information requests should ask a specific question; rejection should explain the decision rather than merely display a red status.
For example, an employee requests read access to reports. Their manager confirms the need, the data owner approves the scope, IT provisions access and the requester verifies it. Approval is not proof that provisioning succeeded: record the execution outcome and arrange revocation at expiry.
4. Keep the architecture small without omitting controls
One option combines a requester portal, an agent work queue, a record database, private file storage and notification processing. Email and chat carry reminders; the request record remains the authoritative status. If email creates tickets, recognize repeated messages to avoid duplicate records.
A failed notification must not erase an accepted request. Separate notification delivery from record creation, bound retries and expose failures to operators. For access provisioning or purchasing integrations, use reference identifiers and outcome checks so retries do not duplicate grants or orders.
Do not put sensitive employee details into shared-channel notifications. Send a request identifier and link, then require authentication and authorization when the recipient opens the record.
5. Authorize records, not just menus
Requesters generally need their own records, agents need assigned scopes, and approvers need requests within their approval responsibility. Sensitive cases need separate policies; a business administrator should not automatically gain access to every record.
OWASP recommends denying access by default and checking permissions on every request. In a portal, changing an ID, calling an API directly or downloading an attachment must still trigger authorization. Hiding interface controls is insufficient.
Record status changes, reassignment and approval decisions without logging passwords or tokens. Define retention, export permissions and access removal after transfers or departure. Test using accounts outside the authorized team, not only an administrator.
6. Define meaningful SLAs and reporting
Separate first response from resolution time. Agree on business hours, holidays, pause conditions and priorities before showing an SLA countdown. An automated receipt acknowledgment should not be treated as a meaningful agent response unless that interpretation has been explicitly agreed.
- Unassigned requests: reveal coordination gaps.
- Age of open work: exposes backlog instead of reporting only closed items.
- Reopen rate: challenges premature closure and weak outcomes.
- Team transfers: highlight classification or ownership ambiguity.
- Time by request type: compares similar work rather than averaging unrelated services.
Capture a baseline using the same definitions and request population before the pilot. Compare trends alongside user feedback. More closed tickets alone do not establish cost savings.
7. Match the delivery model to operating capacity
A subscription service can support a quick trial for common processes; examine export rights, integrations, agent-based costs and exit arrangements. Self-hosting an existing platform needs owners for updates, backup and recovery. Custom development deserves consideration when important process or integration requirements cannot reasonably be met through configuration.
Evaluate each option with the same cases: returned requests, absent approvers, reassignment, integration failure, employee departure and full data export. Include administration, training and maintenance effort, not just acquisition price. This is a decision framework, not a recommendation to purchase a specific product.
8. An illustrative four-week pilot
Adjust this small-scope example to staffing and integration complexity:
- Week 1: choose the pilot team, define three services, confirm owners and collect baseline data.
- Week 2: configure forms, states, permissions and notifications; test unauthorized access, missing information and failed integrations.
- Week 3: accept real requests within the chosen scope, provide user support and review outstanding work daily.
- Week 4: review data quality, user feedback and export/recovery evidence; decide whether to expand, revise or stop.
Keep a fallback intake channel and a reconciliation procedure for requests received during downtime. Do not expand organization-wide before naming both the platform operator and the owner of each service.
9. Go-live checklist
- Every service has an owner, defined inputs and closure criteria.
- Requesters can inspect progress without private status-chasing messages.
- Record access, approval, downloads and exports have been tested across roles.
- Notifications and integrations have visible failure handling.
- Backup evidence includes a restore test, not just a successful backup message.
- A downtime procedure covers alternative intake and reconciliation after recovery.
A good internal request portal is not the one with the most forms. It is the one where responsibility is clear, decisions are explainable and requesters understand the next step. Start small, measure actual outcomes and expand automation deliberately.
No comments yet. Be the first to share your thoughts.